2026
|
Soni, Krishnam; Sehgal, Aditya; Dave*, Vedant; Rückert*, Elmar ALRA: Action-Latent Residual Adaptation for World Models Workshop NeurIPS 2026 Workshop on Towards Test-Time Continual Learning Agents, NeurIPS 2026 Workshop on Continual Learning in the Era of Foundation Models and Embodied Agents, NeurIPS 2026 Workshop on PTA: From Pretrained Representations to Acting Agents, 2026, (* equal supervision). @workshop{krishnamalra2026,
title = {ALRA: Action-Latent Residual Adaptation for World Models},
author = {Krishnam Soni and Aditya Sehgal and Vedant Dave* and Elmar Rückert*},
url = {https://openreview.net/pdf?id=iwZf827hLC},
year = {2026},
date = {2026-09-29},
urldate = {2026-09-29},
publisher = {NeurIPS 2026 Workshop on Towards Test-Time Continual Learning Agents, NeurIPS 2026 Workshop on Continual Learning in the Era of Foundation Models and Embodied Agents, NeurIPS 2026 Workshop on PTA: From Pretrained Representations to Acting Agents},
abstract = {Latent world models degrade when deployed under unseen dynamics shifts. Recent test-time adaptation methods such as AdaJEPA address this by fine-tuning selected sub-networks of the predictor and visual encoder online, updating on the order of 100M parameters within every episode. We show that such updates are unnecessary when the shift acts on the agent's own dynamics: a 210-parameter affine residual applied to the action embedding, with all encoders and the predictor left entirely frozen, recovers as much planning performance as sub-network fine-tuning. On PointMaze-Medium, this residual matches the strongest AdaJEPA baseline under all three shifts: 50x a damping increase, a 0.2x mass reduction, and a 10x mass increase, improving over the frozen baseline in each while leaving in-distribution performance unchanged, and updating four orders of magnitude fewer parameters. Our results suggest that dynamics shifts which rescale how commanded actions translate into motion can be corrected entirely in action space, leaving the learned visual and proprioceptive representation untouched.},
note = {* equal supervision},
keywords = {},
pubstate = {published},
tppubtype = {workshop}
}
Latent world models degrade when deployed under unseen dynamics shifts. Recent test-time adaptation methods such as AdaJEPA address this by fine-tuning selected sub-networks of the predictor and visual encoder online, updating on the order of 100M parameters within every episode. We show that such updates are unnecessary when the shift acts on the agent's own dynamics: a 210-parameter affine residual applied to the action embedding, with all encoders and the predictor left entirely frozen, recovers as much planning performance as sub-network fine-tuning. On PointMaze-Medium, this residual matches the strongest AdaJEPA baseline under all three shifts: 50x a damping increase, a 0.2x mass reduction, and a 10x mass increase, improving over the frozen baseline in each while leaving in-distribution performance unchanged, and updating four orders of magnitude fewer parameters. Our results suggest that dynamics shifts which rescale how commanded actions translate into motion can be corrected entirely in action space, leaving the learned visual and proprioceptive representation untouched. |  |
Gottam, Sai Puneeth Reddy; Rueckert*, Elmar; Dave*, Vedant InfiNoVA: Infinite Novel View Augmentation for Viewpoint Invariant Robot Policies Online 2026, visited: 23.09.2026, (* equal supervision). @online{puneethinfinova2026,
title = {InfiNoVA: Infinite Novel View Augmentation for Viewpoint Invariant Robot Policies},
author = {Sai Puneeth Reddy Gottam and Elmar Rueckert* and Vedant Dave*},
url = {https://arxiv.org/abs/2609.27734v1},
year = {2026},
date = {2026-09-23},
urldate = {2026-09-23},
abstract = {Vision-Language-Action (VLA) policies often rely strongly on the camera viewpoints seen during training, causing substantial performance degradation when deployed from unseen perspectives. Collecting demonstrations from sufficiently diverse physical viewpoints is expensive and still provides only sparse coverage of the viewpoint space. We introduce InfiNoVA, a data-augmentation framework that converts synchronized multi-camera demonstrations into a dense distribution of geometrically consistent training views. InfiNoVA reconstructs each manipulation trajectory as a time-varying 3D Gaussian representation and renders novel observations from sampled camera poses while preserving the original state–action correspondence. This explicit scene representation improves frame-level fidelity and temporal consistency while reducing task-critical hallucinations observed in generative novel-view synthesis. Across four real-world manipulation tasks, policies trained with InfiNoVA achieve 5.4× higher average success under unseen randomized viewpoints than both VISTA-based augmentation and the unaugmented policy. InfiNoVA further achieves 1.7× higher success than training directly on all five physical camera views. These results show that dense, geometrically grounded viewpoint augmentation provides a practical route toward camera-robust robot policies without modifying the underlying policy architecture. },
note = {* equal supervision},
keywords = {},
pubstate = {published},
tppubtype = {online}
}
Vision-Language-Action (VLA) policies often rely strongly on the camera viewpoints seen during training, causing substantial performance degradation when deployed from unseen perspectives. Collecting demonstrations from sufficiently diverse physical viewpoints is expensive and still provides only sparse coverage of the viewpoint space. We introduce InfiNoVA, a data-augmentation framework that converts synchronized multi-camera demonstrations into a dense distribution of geometrically consistent training views. InfiNoVA reconstructs each manipulation trajectory as a time-varying 3D Gaussian representation and renders novel observations from sampled camera poses while preserving the original state–action correspondence. This explicit scene representation improves frame-level fidelity and temporal consistency while reducing task-critical hallucinations observed in generative novel-view synthesis. Across four real-world manipulation tasks, policies trained with InfiNoVA achieve 5.4× higher average success under unseen randomized viewpoints than both VISTA-based augmentation and the unaugmented policy. InfiNoVA further achieves 1.7× higher success than training directly on all five physical camera views. These results show that dense, geometrically grounded viewpoint augmentation provides a practical route toward camera-robust robot policies without modifying the underlying policy architecture. |  |
Soni, Krishnam; Sehgal, Aditya; Dave*, Vedant; Rückert*, Elmar Sandwich-Residuals: Parameter-Efficient Test-time Adaptation of World Models Online 2026, visited: 18.09.2026, (* equal supervision). @online{krishnamresi2026,
title = {Sandwich-Residuals: Parameter-Efficient Test-time Adaptation of World Models},
author = {Krishnam Soni and Aditya Sehgal and Vedant Dave* and Elmar Rückert*},
url = {https://arxiv.org/abs/2609.21740},
year = {2026},
date = {2026-09-18},
urldate = {2026-09-18},
abstract = {Latent world models enable planning by predicting the effects of actions in a learned representation space, but their predictions can become unreliable when test-time conditions differ from training. Existing test-time adaptation methods address this by updating parts of the pretrained model, often modifying millions of parameters and requiring a choice of which internal components to adapt. We introduce SandwichResiduals, a lightweight alternative that keeps the pretrained world model frozen and learns only small residual corrections around the predictor. The residuals are optimized online using the model’s self-supervised prediction error and require no rewards, labels, or source-domain data. Across 21 conditions on the AdaJEPA benchmark, our method achieves 1.3× the success rate of the frozen model while retaining 95% of the performance of the strongest AdaJEPA variant and adapting 97–99% fewer parameters. Under compound shifts, this advantage increases to 1.9× the success rate of the frozen model, while remaining comparable to internal block adaptation. We further demonstrate the same adaptation principle on a DINO-WM model for 3-D manipulation. These results suggest that effective test-time adaptation of world models does not necessarily require modifying their pretrained internal weights.},
note = {* equal supervision},
keywords = {},
pubstate = {published},
tppubtype = {online}
}
Latent world models enable planning by predicting the effects of actions in a learned representation space, but their predictions can become unreliable when test-time conditions differ from training. Existing test-time adaptation methods address this by updating parts of the pretrained model, often modifying millions of parameters and requiring a choice of which internal components to adapt. We introduce SandwichResiduals, a lightweight alternative that keeps the pretrained world model frozen and learns only small residual corrections around the predictor. The residuals are optimized online using the model’s self-supervised prediction error and require no rewards, labels, or source-domain data. Across 21 conditions on the AdaJEPA benchmark, our method achieves 1.3× the success rate of the frozen model while retaining 95% of the performance of the strongest AdaJEPA variant and adapting 97–99% fewer parameters. Under compound shifts, this advantage increases to 1.9× the success rate of the frozen model, while remaining comparable to internal block adaptation. We further demonstrate the same adaptation principle on a DINO-WM model for 3-D manipulation. These results suggest that effective test-time adaptation of world models does not necessarily require modifying their pretrained internal weights. | 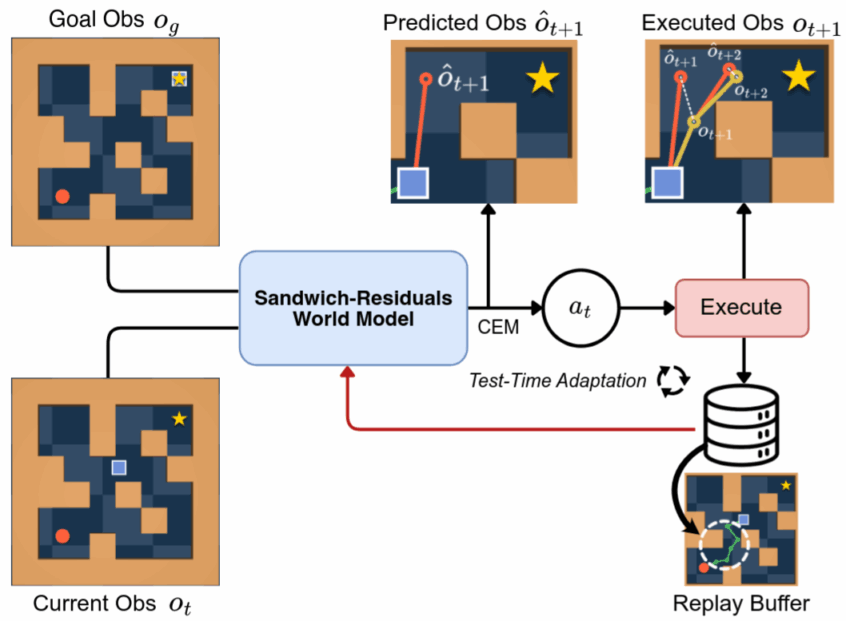 |
Dave, Vedant; Rauch, Christian; Rückert, Elmar Task-Relevant Language-conditioned Segmentation for Robust Generalization in Reinforcement Learning Journal Article In: Transactions on Machine Learning Research, 2026. @article{dave2026learning,
title = {Task-Relevant Language-conditioned Segmentation for Robust Generalization in Reinforcement Learning},
author = {Vedant Dave and Christian Rauch and Elmar Rückert},
url = {https://openreview.net/forum?id=MRHXB6eooE},
year = {2026},
date = {2026-07-03},
journal = {Transactions on Machine Learning Research},
keywords = {},
pubstate = {published},
tppubtype = {article}
}
|  |
2025
|
Keshavarz, Sahar; Elmgerbi, Asad; Dave, Vedant; Rückert, Elmar; Thonhauser, Gerhard Deep reinforcement learning for automated decision-making in wellbore construction Journal Article In: Energy Reports, vol. 14, pp. 3514-3528, 2025, ISSN: 2352-4847. @article{KESHAVARZ20253514,
title = {Deep reinforcement learning for automated decision-making in wellbore construction},
author = {Sahar Keshavarz and Asad Elmgerbi and Vedant Dave and Elmar Rückert and Gerhard Thonhauser},
url = {https://cloud.cps.unileoben.ac.at/index.php/s/X9wYbSpemJqrkW8},
doi = {https://doi.org/10.1016/j.egyr.2025.10.028},
issn = {2352-4847},
year = {2025},
date = {2025-11-02},
urldate = {2025-11-02},
journal = {Energy Reports},
volume = {14},
pages = {3514-3528},
abstract = {The drilling industry continuously seeks cost reduction through improved efficiency, with automation seen as a key solution. The drilling industry continuously seeks cost reduction through improved efficiency, with automation viewed as a key enabler. However, due to the complexity of drilling operations, uncertainty in subsurface conditions, and limitations in real-time data, achieving reliable autonomy remains a major challenge. While physics-based models support automation, they often face limitations under real-time constraints and may struggle to adapt effectively in the presence of uncertain or incomplete data. This study contributes to automation efforts by employing Reinforcement Learning (RL) to model hole conditioning, an essential part of drilling operation. Using a Q-learning approach, the RL agent optimizes operational decisions in real time, adapting based on environmental feedback. This artificial intelligence (AI) -driven agent identifies the ideal sequence of actions for circulation, reaming, and washing, maximizing operational safety and efficiency by aligning with target parameters while navigating operational constraints. The RL model decisions were benchmarked against real-case actions, demonstrating that the agent strategy can outperform expert choices in several areas. Specifically, the RL model provided better solutions in three key examples: avoiding poor hole cleaning, lowering the operational time, and preventing wellbore stability issues. The proposed system contributes to the growing body of research applying deep reinforcement learning for automated hole conditioning, representing an innovative engineering application for AI. This approach not only enhances real-time decision-making capabilities but also establishes a foundation for further automation in well construction, integrating engineering requirements with advanced AI-driven strategies. Through the combination of AI and practical engineering design, this work advances both automation and safety in drilling operations, signaling a promising step forward for future developments in wellbore construction.},
keywords = {},
pubstate = {published},
tppubtype = {article}
}
The drilling industry continuously seeks cost reduction through improved efficiency, with automation seen as a key solution. The drilling industry continuously seeks cost reduction through improved efficiency, with automation viewed as a key enabler. However, due to the complexity of drilling operations, uncertainty in subsurface conditions, and limitations in real-time data, achieving reliable autonomy remains a major challenge. While physics-based models support automation, they often face limitations under real-time constraints and may struggle to adapt effectively in the presence of uncertain or incomplete data. This study contributes to automation efforts by employing Reinforcement Learning (RL) to model hole conditioning, an essential part of drilling operation. Using a Q-learning approach, the RL agent optimizes operational decisions in real time, adapting based on environmental feedback. This artificial intelligence (AI) -driven agent identifies the ideal sequence of actions for circulation, reaming, and washing, maximizing operational safety and efficiency by aligning with target parameters while navigating operational constraints. The RL model decisions were benchmarked against real-case actions, demonstrating that the agent strategy can outperform expert choices in several areas. Specifically, the RL model provided better solutions in three key examples: avoiding poor hole cleaning, lowering the operational time, and preventing wellbore stability issues. The proposed system contributes to the growing body of research applying deep reinforcement learning for automated hole conditioning, representing an innovative engineering application for AI. This approach not only enhances real-time decision-making capabilities but also establishes a foundation for further automation in well construction, integrating engineering requirements with advanced AI-driven strategies. Through the combination of AI and practical engineering design, this work advances both automation and safety in drilling operations, signaling a promising step forward for future developments in wellbore construction. |  |
Dave, Vedant; Özdenizci, Ozan; Rückert, Elmar Learning Robust Representations for Visual Reinforcement Learning via Task-Relevant Mask Sampling Journal Article In: Transactions on Machine Learning Research, 2025. @article{dave2025learning,
title = {Learning Robust Representations for Visual Reinforcement Learning via Task-Relevant Mask Sampling},
author = {Vedant Dave and Ozan Özdenizci and Elmar Rückert},
url = {https://openreview.net/pdf?id=2rxNDxHwtn},
year = {2025},
date = {2025-09-18},
urldate = {2025-08-11},
journal = {Transactions on Machine Learning Research},
keywords = {},
pubstate = {published},
tppubtype = {article}
}
|  |
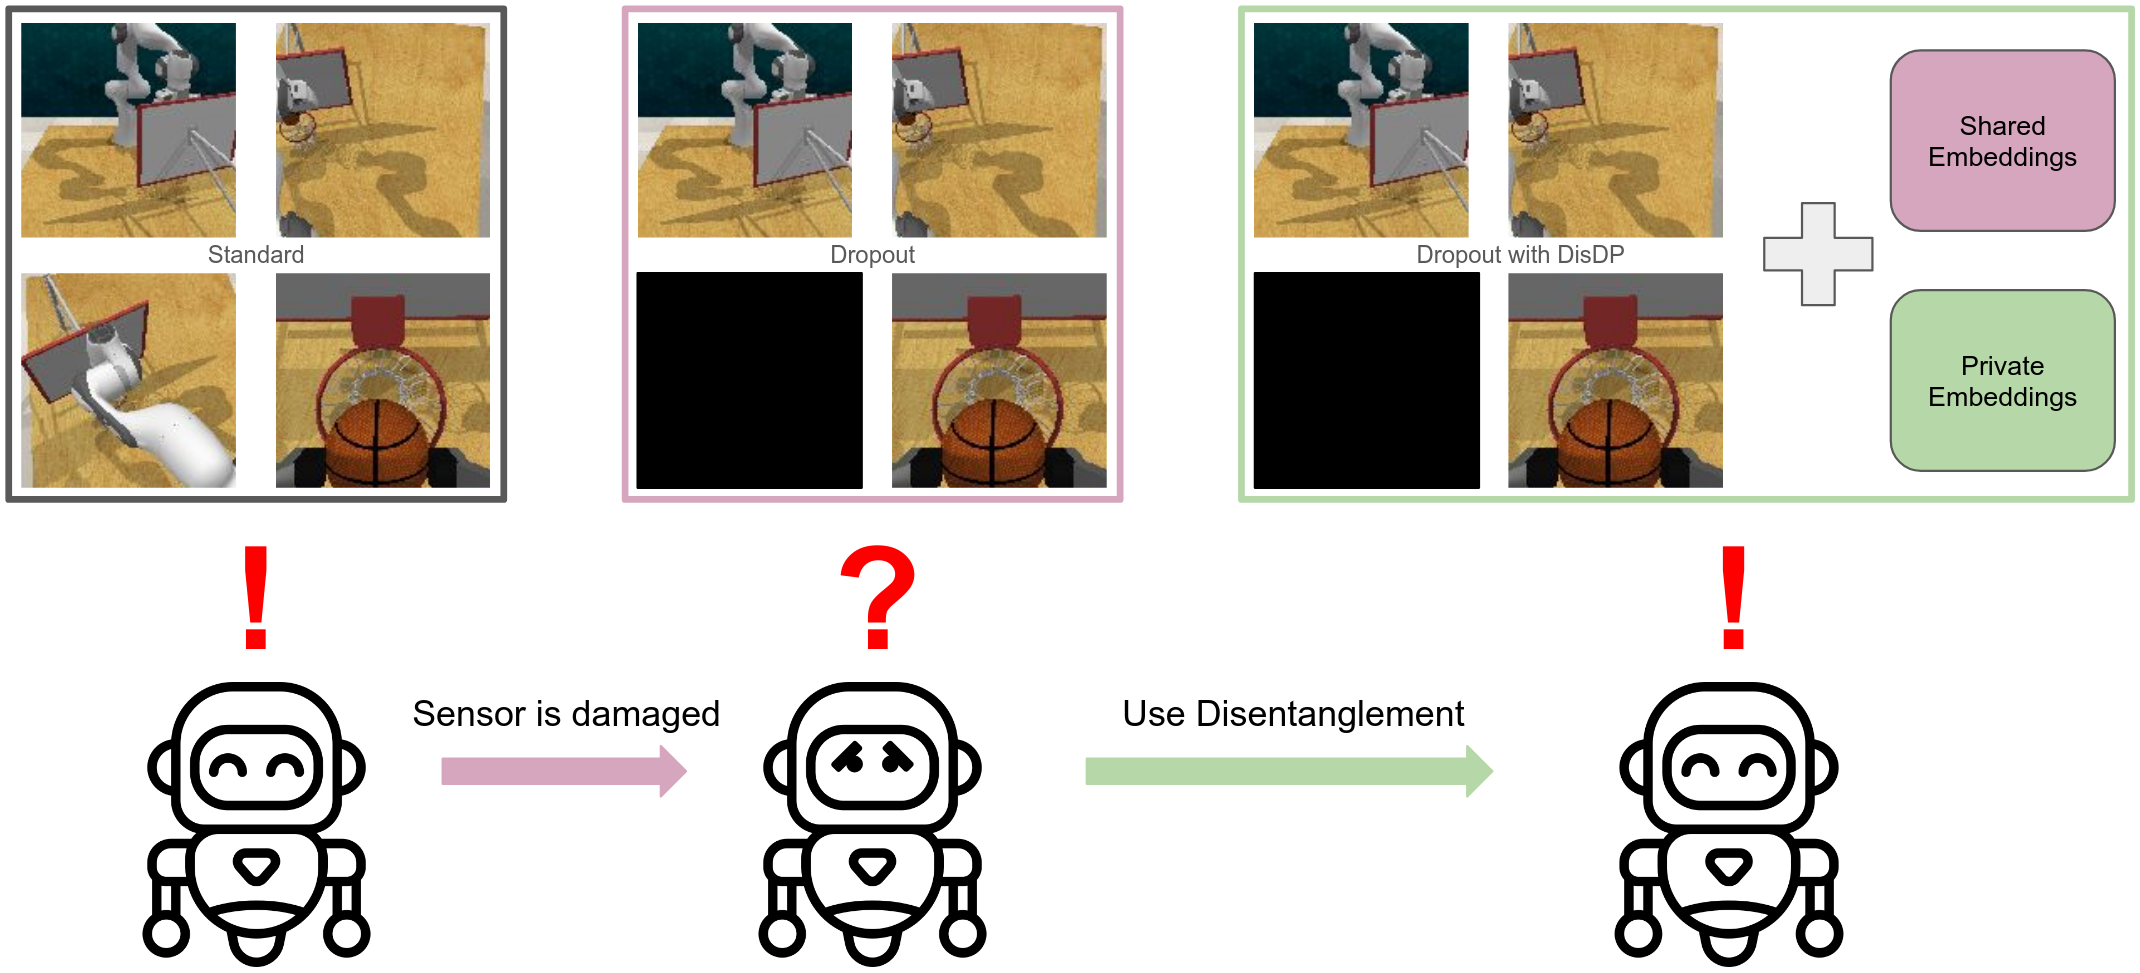
Vanjani, Pankhuri; Mattes, Paul; Li, Maximilian Xiling; Dave, Vedant; Lioutikov, Rudolf DisDP: Robust Imitation Learning via Disentangled Diffusion Policies Proceedings Article In: Reinforcement Learning Conference (RLC), Reinforcement Learning Journal, 2025. @inproceedings{dave2025disdp,
title = {DisDP: Robust Imitation Learning via Disentangled Diffusion Policies},
author = {Pankhuri Vanjani and Paul Mattes and Maximilian Xiling Li and Vedant Dave and Rudolf Lioutikov},
url = {https://openreview.net/pdf?id=0GSL9VRBib},
year = {2025},
date = {2025-05-10},
urldate = {2025-05-10},
booktitle = {Reinforcement Learning Conference (RLC)},
publisher = {Reinforcement Learning Journal},
keywords = {},
pubstate = {published},
tppubtype = {inproceedings}
}
|  |
Dave, Vedant; Rueckert, Elmar Skill Disentanglement in Reproducing Kernel Hilbert Space Proceedings Article In: Proceedings of the AAAI Conference on Artificial Intelligence (AAAI), pp. 16153-16162, 2025. @inproceedings{Dave2025bb,
title = {Skill Disentanglement in Reproducing Kernel Hilbert Space},
author = {Vedant Dave and Elmar Rueckert
},
url = {https://cloud.cps.unileoben.ac.at/index.php/s/m9XKo4t2FXAH6Cs},
doi = {https://doi.org/10.1609/aaai.v39i15.33774},
year = {2025},
date = {2025-04-11},
urldate = {2025-02-27},
booktitle = {Proceedings of the AAAI Conference on Artificial Intelligence (AAAI)},
volume = {39},
number = {15},
pages = {16153-16162},
abstract = {Unsupervised Skill Discovery aims at learning diverse skills without any extrinsic rewards and leverage them as prior for learning a variety of downstream tasks. Existing approaches to unsupervised reinforcement learning typically involve discovering skills through empowerment-driven techniques or by maximizing entropy to encourage exploration. However, this mutual information objective often results in either static skills that discourage exploration or maximise coverage at the expense of non-discriminable skills. Instead of focusing only on maximizing bounds on f-divergence, we combine it with Integral Probability Metrics to maximize the distance between distributions to promote behavioural diversity and enforce disentanglement. Our method, Hilbert Unsupervised Skill Discovery (HUSD), provides an additional objective that seeks to obtain exploration and separability of state-skill pairs by maximizing the Maximum Mean Discrepancy between the joint distribution of skills and states and the product of their marginals in Reproducing Kernel Hilbert Space. Our results on Unsupervised RL Benchmark show that HUSD outperforms previous exploration algorithms on state-based tasks.},
keywords = {},
pubstate = {published},
tppubtype = {inproceedings}
}
Unsupervised Skill Discovery aims at learning diverse skills without any extrinsic rewards and leverage them as prior for learning a variety of downstream tasks. Existing approaches to unsupervised reinforcement learning typically involve discovering skills through empowerment-driven techniques or by maximizing entropy to encourage exploration. However, this mutual information objective often results in either static skills that discourage exploration or maximise coverage at the expense of non-discriminable skills. Instead of focusing only on maximizing bounds on f-divergence, we combine it with Integral Probability Metrics to maximize the distance between distributions to promote behavioural diversity and enforce disentanglement. Our method, Hilbert Unsupervised Skill Discovery (HUSD), provides an additional objective that seeks to obtain exploration and separability of state-skill pairs by maximizing the Maximum Mean Discrepancy between the joint distribution of skills and states and the product of their marginals in Reproducing Kernel Hilbert Space. Our results on Unsupervised RL Benchmark show that HUSD outperforms previous exploration algorithms on state-based tasks. |  |
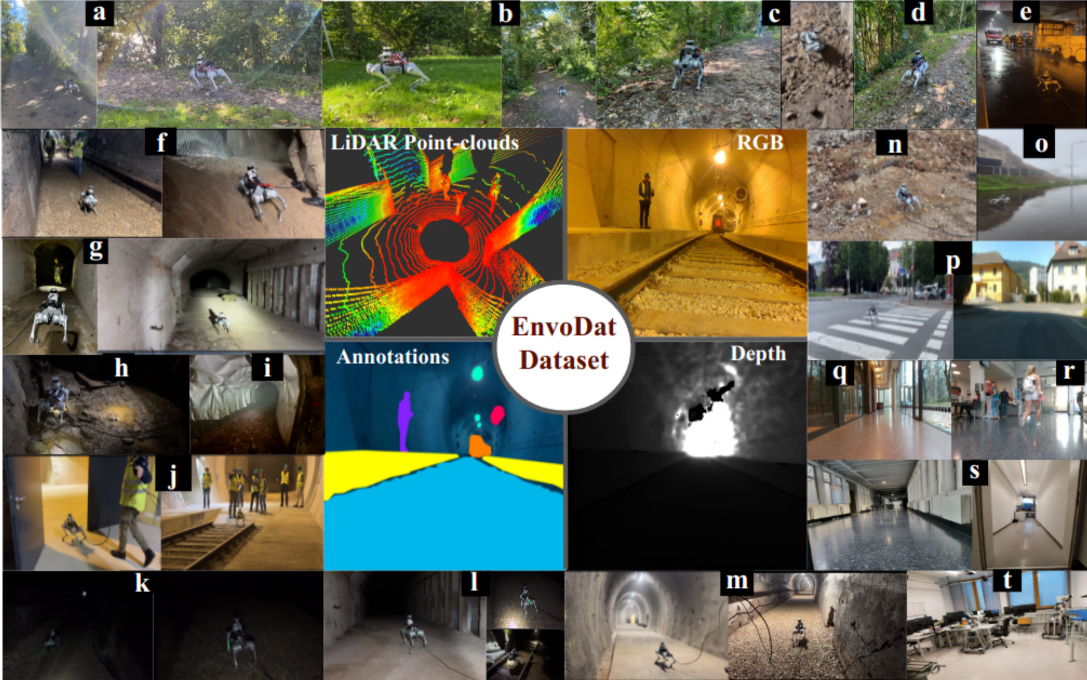
Nwankwo, Linus; Ellensohn, Bjoern; Dave, Vedant; Hofer, Peter; Forstner, Jan; Villneuve, Marlene; Galler, Robert; Rueckert, Elmar EnvoDat: A Large-Scale Multisensory Dataset for Robotic Spatial Awareness and Semantic Reasoning in Heterogeneous Environments Proceedings Article In: IEEE International Conference on Robotics and Automation (ICRA 2025)., 2025. @inproceedings{Nwankwo2025,
title = {EnvoDat: A Large-Scale Multisensory Dataset for Robotic Spatial Awareness and Semantic Reasoning in Heterogeneous Environments},
author = {Linus Nwankwo and Bjoern Ellensohn and Vedant Dave and Peter Hofer and Jan Forstner and Marlene Villneuve and Robert Galler and Elmar Rueckert},
url = {https://cloud.cps.unileoben.ac.at/index.php/s/MawgtYSbTBoNBZo},
year = {2025},
date = {2025-01-27},
urldate = {2025-01-27},
booktitle = {IEEE International Conference on Robotics and Automation (ICRA 2025).},
keywords = {},
pubstate = {published},
tppubtype = {inproceedings}
}
|  |
2024
|
Dave, Vedant; Rueckert, Elmar Denoised Predictive Imagination: An Information-theoretic approach for learning World Models Conference European Workshop on Reinforcement Learning (EWRL), 2024. @conference{dpidave2024,
title = {Denoised Predictive Imagination: An Information-theoretic approach for learning World Models},
author = {Vedant Dave and Elmar Rueckert},
url = {https://cps.unileoben.ac.at/wp/135_Denoised_Predictive_Imagin.pdf},
year = {2024},
date = {2024-08-01},
urldate = {2024-08-01},
publisher = {European Workshop on Reinforcement Learning (EWRL)},
abstract = {Humans excel at isolating relevant information from noisy data to predict the behavior of dynamic systems, effectively disregarding non-informative, temporally-correlated noise. In contrast, existing reinforcement learning algorithms face challenges in generating noise-free predictions within high-dimensional, noise-saturated environments, especially when trained on world models featuring realistic background noise extracted from natural video streams. We propose a novel information-theoretic approach that learn world models based on minimising the past information and retaining maximal information about the future, aiming at simultaneously learning control policies and at producing denoised predictions. Utilizing Soft Actor-Critic agents augmented with an information-theoretic auxiliary loss, we validate our method's effectiveness on complex variants of the standard DeepMind Control Suite tasks, where natural videos filled with intricate and task-irrelevant information serve as a background. Experimental results demonstrate that our model outperforms nine state-of-the-art approaches in various settings where natural videos serve as dynamic background noise. Our analysis also reveals that all these methods encounter challenges in more complex environments.},
keywords = {},
pubstate = {published},
tppubtype = {conference}
}
Humans excel at isolating relevant information from noisy data to predict the behavior of dynamic systems, effectively disregarding non-informative, temporally-correlated noise. In contrast, existing reinforcement learning algorithms face challenges in generating noise-free predictions within high-dimensional, noise-saturated environments, especially when trained on world models featuring realistic background noise extracted from natural video streams. We propose a novel information-theoretic approach that learn world models based on minimising the past information and retaining maximal information about the future, aiming at simultaneously learning control policies and at producing denoised predictions. Utilizing Soft Actor-Critic agents augmented with an information-theoretic auxiliary loss, we validate our method's effectiveness on complex variants of the standard DeepMind Control Suite tasks, where natural videos filled with intricate and task-irrelevant information serve as a background. Experimental results demonstrate that our model outperforms nine state-of-the-art approaches in various settings where natural videos serve as dynamic background noise. Our analysis also reveals that all these methods encounter challenges in more complex environments. | 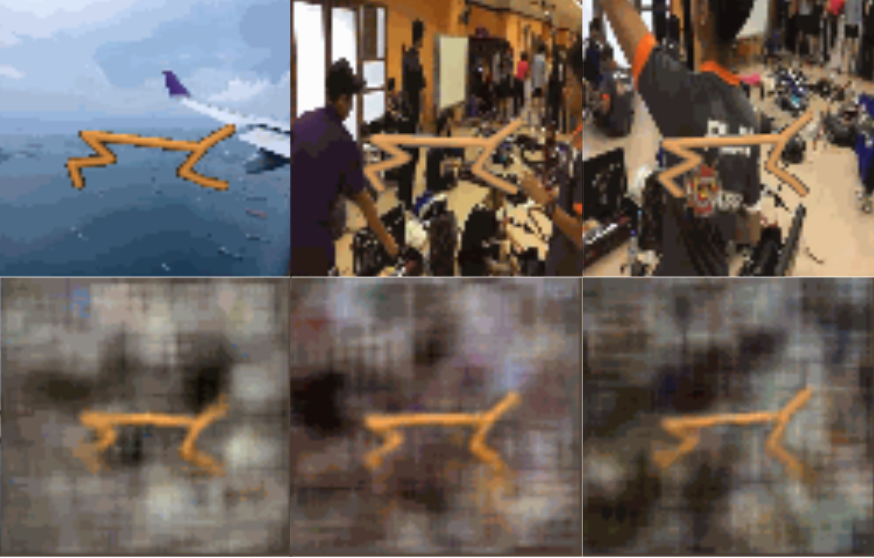 |
Lygerakis, Fotios; Dave, Vedant; Rueckert, Elmar M2CURL: Sample-Efficient Multimodal Reinforcement Learning via Self-Supervised Representation Learning for Robotic Manipulation Proceedings Article In: IEEE International Conference on Ubiquitous Robots (UR 2024), IEEE 2024. @inproceedings{Lygerakis2024,
title = {M2CURL: Sample-Efficient Multimodal Reinforcement Learning via Self-Supervised Representation Learning for Robotic Manipulation},
author = {Fotios Lygerakis and Vedant Dave and Elmar Rueckert},
url = {https://cloud.cps.unileoben.ac.at/index.php/s/NPejb2Fp4Y8LeyZ},
year = {2024},
date = {2024-04-04},
urldate = {2024-04-04},
booktitle = {IEEE International Conference on Ubiquitous Robots (UR 2024)},
organization = {IEEE},
keywords = {},
pubstate = {published},
tppubtype = {inproceedings}
}
|  |
Dave*, Vedant; Lygerakis*, Fotios; Rueckert, Elmar Multimodal Visual-Tactile Representation Learning through Self-Supervised Contrastive Pre-Training Proceedings Article In: IEEE International Conference on Robotics and Automation (ICRA), pp. 8013-8020, IEEE, 2024, ISBN: 979-8-3503-8457-4, (* equal contribution). @inproceedings{Dave2024b,
title = {Multimodal Visual-Tactile Representation Learning through Self-Supervised Contrastive Pre-Training},
author = {Vedant Dave* and Fotios Lygerakis* and Elmar Rueckert},
url = {https://cloud.cps.unileoben.ac.at/index.php/s/Nw9TprfdDoLgr8e},
doi = {10.1109/ICRA57147.2024.10610228},
isbn = {979-8-3503-8457-4},
year = {2024},
date = {2024-01-28},
urldate = {2024-01-28},
booktitle = {IEEE International Conference on Robotics and Automation (ICRA)},
pages = {8013-8020},
publisher = {IEEE},
abstract = {The rapidly evolving field of robotics necessitates methods that can facilitate the fusion of multiple modalities. Specifically, when it comes to interacting with tangible objects, effectively combining visual and tactile sensory data is key to understanding and navigating the complex dynamics of the physical world, enabling a more nuanced and adaptable response to changing environments. Nevertheless, much of the earlier work in merging these two sensory modalities has relied on supervised methods utilizing datasets labeled by humans. This paper introduces MViTac, a novel methodology that leverages contrastive learning to integrate vision and touch sensations in a self-supervised fashion. By availing both sensory inputs, MViTac leverages intra and inter-modality losses for learning representations, resulting in enhanced material property classification and more adept grasping prediction. Through a series of experiments, we showcase the effectiveness of our method and its superiority over existing state-of-the-art self-supervised and supervised techniques. In evaluating our methodology, we focus on two distinct tasks: material classification and grasping success prediction. Our results indicate that MViTac facilitates the development of improved modality encoders, yielding more robust representations as evidenced by linear probing assessments. https://sites.google.com/view/mvitac/home},
note = {* equal contribution},
keywords = {},
pubstate = {published},
tppubtype = {inproceedings}
}
The rapidly evolving field of robotics necessitates methods that can facilitate the fusion of multiple modalities. Specifically, when it comes to interacting with tangible objects, effectively combining visual and tactile sensory data is key to understanding and navigating the complex dynamics of the physical world, enabling a more nuanced and adaptable response to changing environments. Nevertheless, much of the earlier work in merging these two sensory modalities has relied on supervised methods utilizing datasets labeled by humans. This paper introduces MViTac, a novel methodology that leverages contrastive learning to integrate vision and touch sensations in a self-supervised fashion. By availing both sensory inputs, MViTac leverages intra and inter-modality losses for learning representations, resulting in enhanced material property classification and more adept grasping prediction. Through a series of experiments, we showcase the effectiveness of our method and its superiority over existing state-of-the-art self-supervised and supervised techniques. In evaluating our methodology, we focus on two distinct tasks: material classification and grasping success prediction. Our results indicate that MViTac facilitates the development of improved modality encoders, yielding more robust representations as evidenced by linear probing assessments. https://sites.google.com/view/mvitac/home |  |
2022
|
Dave, Vedant; Rueckert, Elmar Can we infer the full-arm manipulation skills from tactile targets? Conference Workshop paper at the International Conference on Humanoids, WS title: Advances in Close Proximity Human-Robot Collaboration, International Conference on Humanoid Robots (Humanoids), 2022. @conference{Dave2022WS,
title = {Can we infer the full-arm manipulation skills from tactile targets?},
author = {Vedant Dave and Elmar Rueckert},
url = {https://cloud.cps.unileoben.ac.at/index.php/f/562953},
year = {2022},
date = {2022-11-28},
urldate = {2022-11-28},
booktitle = {Workshop paper at the International Conference on Humanoids, WS title: Advances in Close Proximity Human-Robot Collaboration},
publisher = {International Conference on Humanoid Robots (Humanoids)},
abstract = {Tactile sensing provides significant information about the state of the environment for performing manipulation tasks. Manipulation skills depends on the desired initial contact points between the object and the end-effector. Based on physical properties of the object, this contact results into distinct tactile responses. We propose Tactile Probabilistic Movement Primitives (TacProMPs), to learn a highly non-linear relationship between the desired tactile responses and the full-arm movement, where we condition solely on the tactile responses to infer the complex manipulation skills. We use a Gaussian mixture model of primitives to address the multimodality in demonstrations. We demonstrate the performance of our method in challenging real-world scenarios.},
keywords = {},
pubstate = {published},
tppubtype = {conference}
}
Tactile sensing provides significant information about the state of the environment for performing manipulation tasks. Manipulation skills depends on the desired initial contact points between the object and the end-effector. Based on physical properties of the object, this contact results into distinct tactile responses. We propose Tactile Probabilistic Movement Primitives (TacProMPs), to learn a highly non-linear relationship between the desired tactile responses and the full-arm movement, where we condition solely on the tactile responses to infer the complex manipulation skills. We use a Gaussian mixture model of primitives to address the multimodality in demonstrations. We demonstrate the performance of our method in challenging real-world scenarios. | 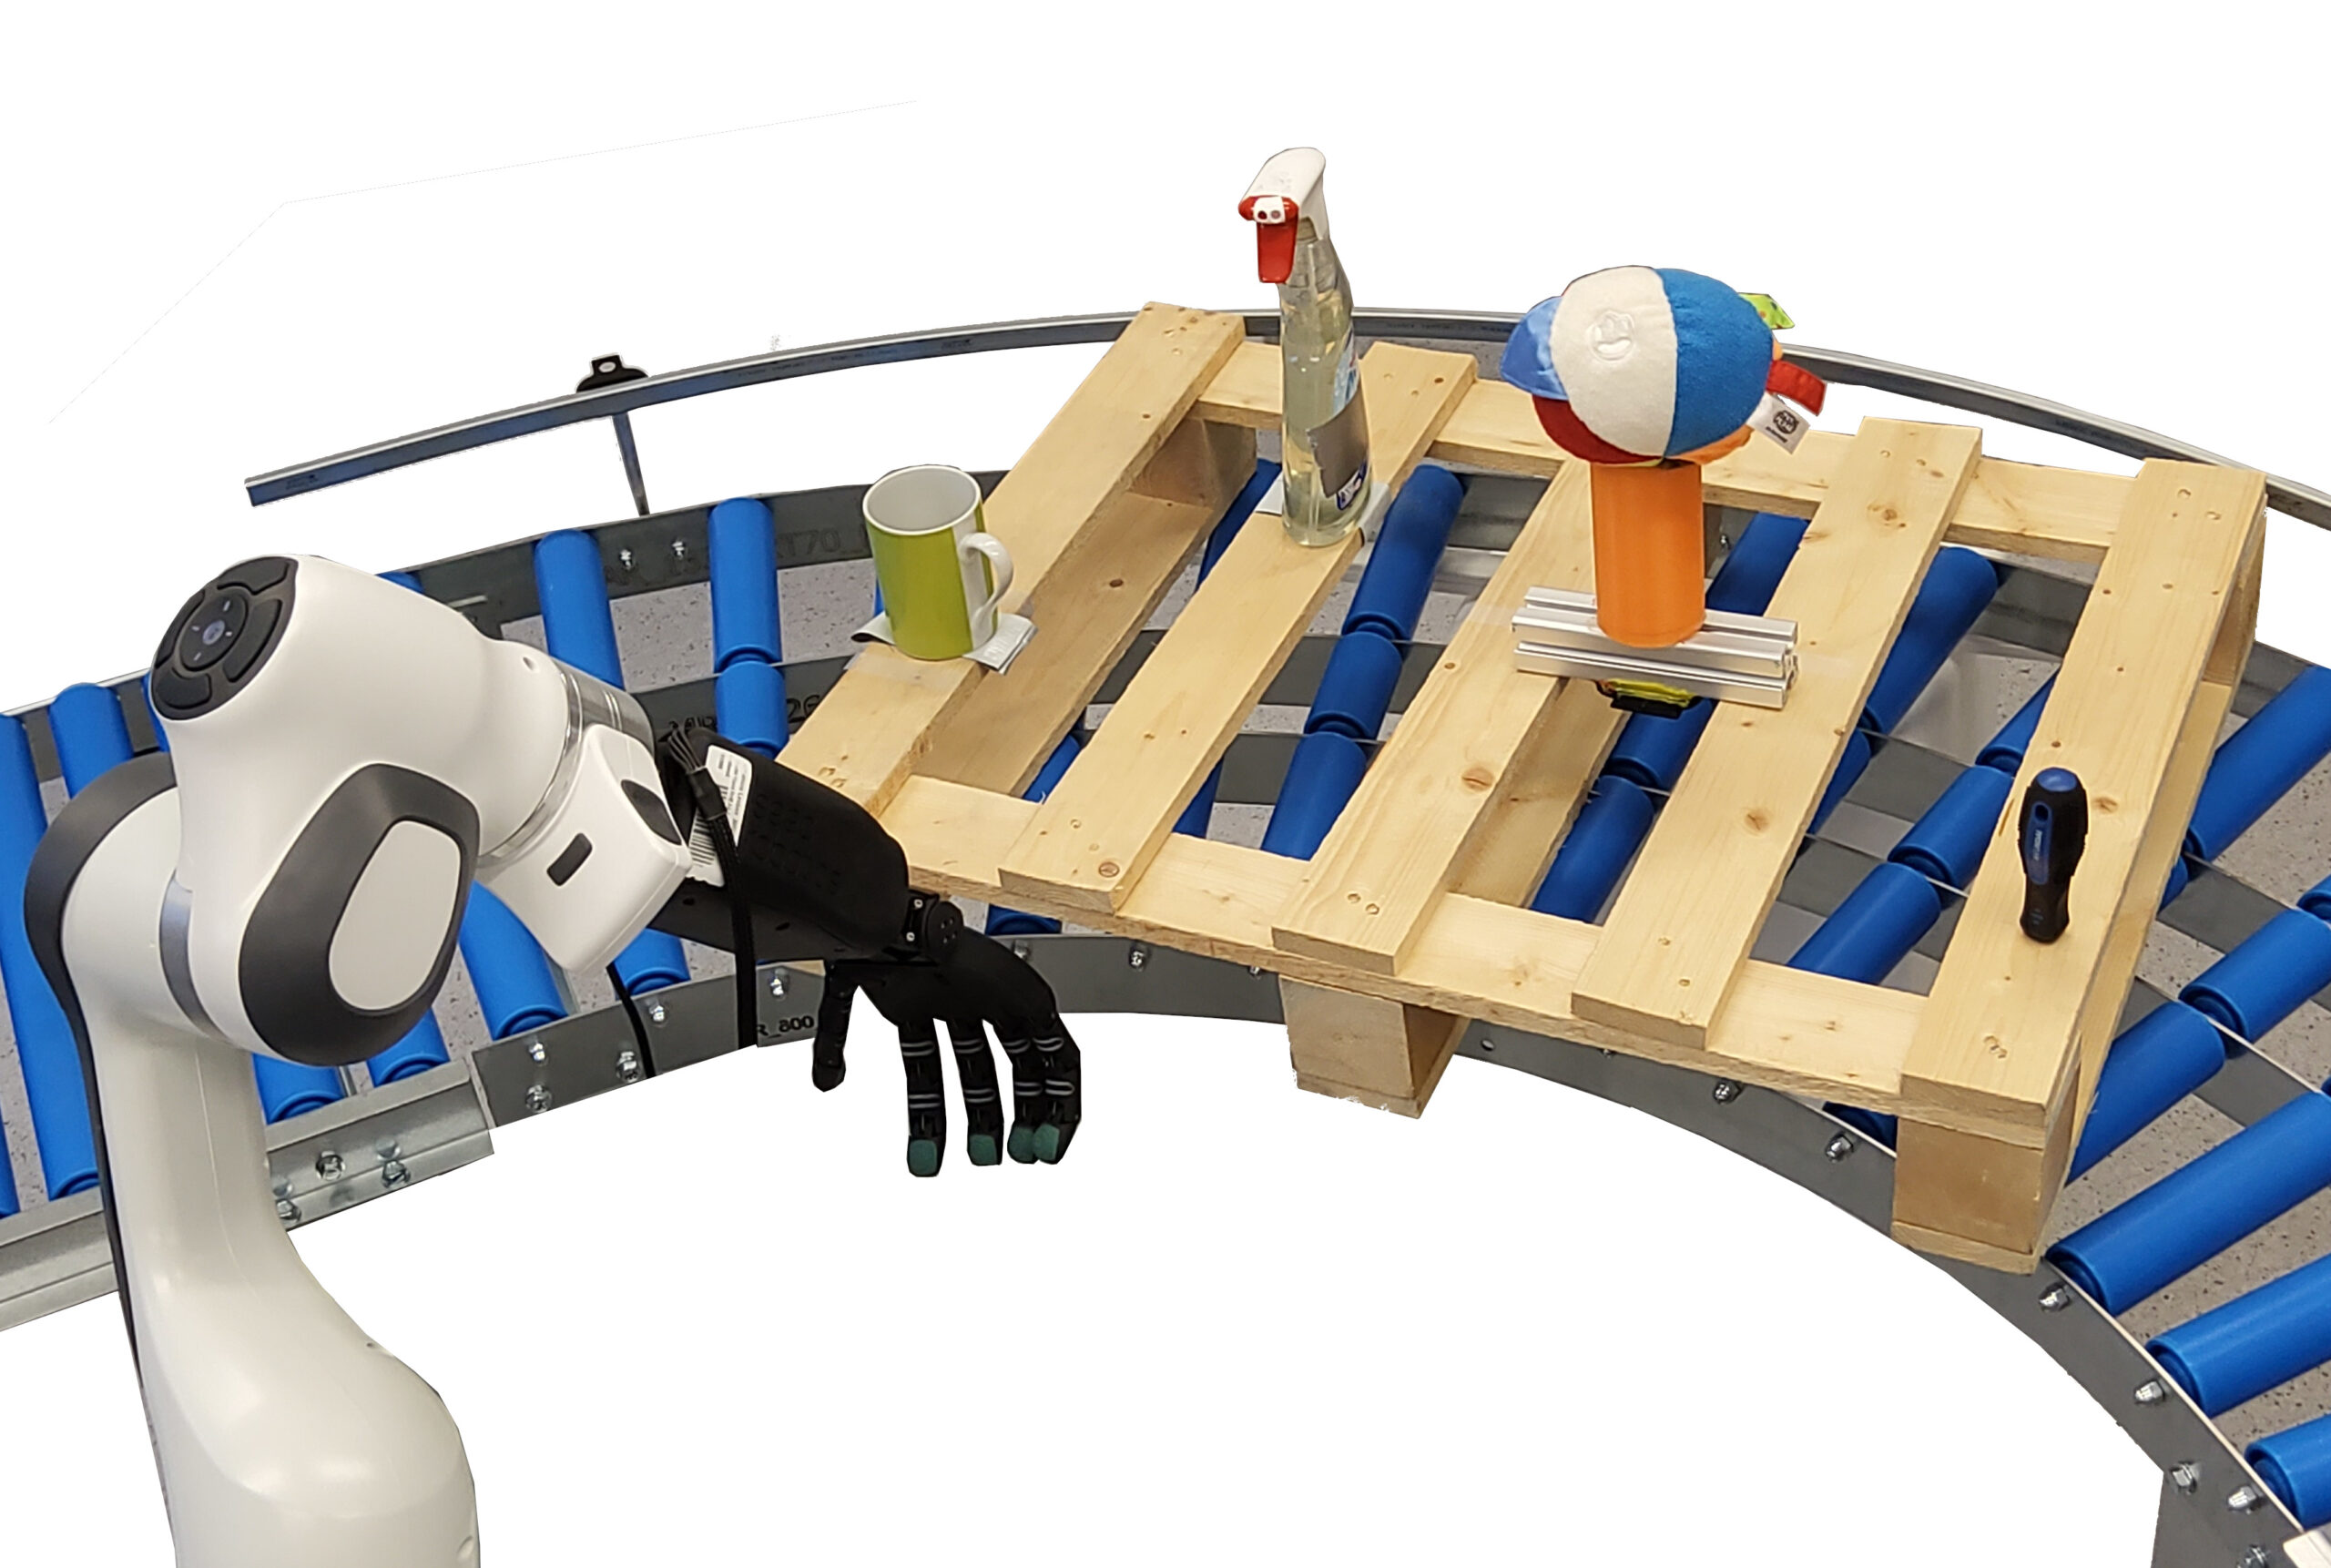 |
Dave, Vedant; Rueckert, Elmar Predicting full-arm grasping motions from anticipated tactile responses Proceedings Article In: International Conference on Humanoid Robots (Humanoids), pp. 464-471, IEEE, 2022, ISBN: 979-8-3503-0979-9. @inproceedings{Dave2022,
title = {Predicting full-arm grasping motions from anticipated tactile responses},
author = {Vedant Dave and Elmar Rueckert},
url = {https://cloud.cps.unileoben.ac.at/index.php/s/WzGSNtc5WRLN3EL},
doi = {10.1109/Humanoids53995.2022.9999743},
isbn = {979-8-3503-0979-9},
year = {2022},
date = {2022-09-26},
urldate = {2022-09-26},
booktitle = {International Conference on Humanoid Robots (Humanoids)},
pages = {464-471},
publisher = {IEEE},
abstract = {Tactile sensing provides significant information about the state of the environment for performing manipulation tasks. Depending on the physical properties of the object, manipulation tasks can exhibit large variation in their movements. For a grasping task, the movement of the arm and of the end effector varies depending on different points of contact on the object, especially if the object is non-homogeneous in hardness and/or has an uneven geometry. In this paper, we propose Tactile Probabilistic Movement Primitives (TacProMPs), to learn a highly non-linear relationship between the desired tactile responses and the full-arm movement. We solely condition on the tactile responses to infer the complex manipulation skills. We formulate a joint trajectory of full-arm joints with tactile data, leverage the model to condition on the desired tactile response from the non-homogeneous object and infer the full-arm (7-dof panda arm and 19-dof gripper hand) motion. We use a Gaussian Mixture Model of primitives to address the multimodality in demonstrations. We also show that the measurement noise adjustment must be taken into account due to multiple systems working in collaboration.
We validate and show the robustness of the approach through two experiments. First, we consider an object with non-uniform hardness. Grasping from different locations require different motion, and results into different tactile responses. Second, we have an object with homogeneous hardness, but we grasp it with widely varying grasping configurations. Our result shows that TacProMPs can successfully model complex multimodal skills and generalise to new situations.},
keywords = {},
pubstate = {published},
tppubtype = {inproceedings}
}
Tactile sensing provides significant information about the state of the environment for performing manipulation tasks. Depending on the physical properties of the object, manipulation tasks can exhibit large variation in their movements. For a grasping task, the movement of the arm and of the end effector varies depending on different points of contact on the object, especially if the object is non-homogeneous in hardness and/or has an uneven geometry. In this paper, we propose Tactile Probabilistic Movement Primitives (TacProMPs), to learn a highly non-linear relationship between the desired tactile responses and the full-arm movement. We solely condition on the tactile responses to infer the complex manipulation skills. We formulate a joint trajectory of full-arm joints with tactile data, leverage the model to condition on the desired tactile response from the non-homogeneous object and infer the full-arm (7-dof panda arm and 19-dof gripper hand) motion. We use a Gaussian Mixture Model of primitives to address the multimodality in demonstrations. We also show that the measurement noise adjustment must be taken into account due to multiple systems working in collaboration.
We validate and show the robustness of the approach through two experiments. First, we consider an object with non-uniform hardness. Grasping from different locations require different motion, and results into different tactile responses. Second, we have an object with homogeneous hardness, but we grasp it with widely varying grasping configurations. Our result shows that TacProMPs can successfully model complex multimodal skills and generalise to new situations. | 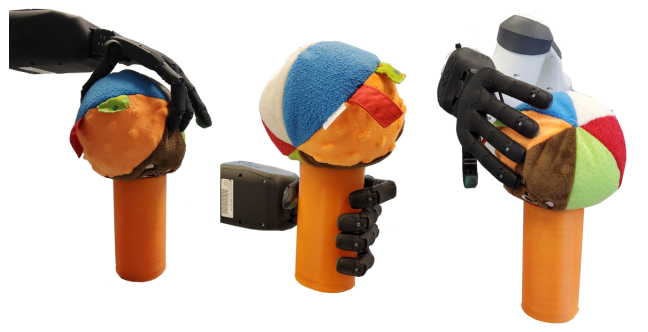 |
Leonel, Rozo*; Vedant, Dave* Orientation Probabilistic Movement Primitives on Riemannian Manifolds Proceedings Article In: Conference on Robot Learning (CoRL), pp. 11, 2022, (* equal contribution). @inproceedings{Leonel2022,
title = {Orientation Probabilistic Movement Primitives on Riemannian Manifolds},
author = {Leonel, Rozo* and Vedant, Dave*},
url = {https://cps.unileoben.ac.at/wp/orientation_probabilistic_move.pdf, Article File},
year = {2022},
date = {2022-01-11},
urldate = {2022-01-11},
booktitle = {Conference on Robot Learning (CoRL)},
volume = {164},
pages = {11},
abstract = {Learning complex robot motions necessarily demands to have models that are able to encode and retrieve full-pose trajectories when tasks are defined in operational spaces. Probabilistic movement primitives (ProMPs) stand out as a principled approach that models trajectory distributions learned from demonstrations. ProMPs allow for trajectory modulation and blending to achieve better generalization to novel situations. However, when ProMPs are employed in operational space, their original formulation does not directly apply to full-pose movements including rotational trajectories described by quaternions. This paper proposes a Riemannian formulation of ProMPs that enables encoding and retrieving of quaternion trajectories. Our method builds on Riemannian manifold theory,
and exploits multilinear geodesic regression for estimating the ProMPs parameters. This novel approach makes ProMPs a suitable model for learning complex full-pose robot motion patterns. Riemannian ProMPs are tested on toy examples to illustrate their workflow, and on real learning-from-demonstration experiments.},
note = {* equal contribution},
keywords = {},
pubstate = {published},
tppubtype = {inproceedings}
}
Learning complex robot motions necessarily demands to have models that are able to encode and retrieve full-pose trajectories when tasks are defined in operational spaces. Probabilistic movement primitives (ProMPs) stand out as a principled approach that models trajectory distributions learned from demonstrations. ProMPs allow for trajectory modulation and blending to achieve better generalization to novel situations. However, when ProMPs are employed in operational space, their original formulation does not directly apply to full-pose movements including rotational trajectories described by quaternions. This paper proposes a Riemannian formulation of ProMPs that enables encoding and retrieving of quaternion trajectories. Our method builds on Riemannian manifold theory,
and exploits multilinear geodesic regression for estimating the ProMPs parameters. This novel approach makes ProMPs a suitable model for learning complex full-pose robot motion patterns. Riemannian ProMPs are tested on toy examples to illustrate their workflow, and on real learning-from-demonstration experiments. | 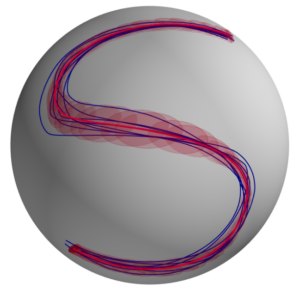 |